

Programming, graphics, games, media, C++, Windows, Internet and more...
Entries for tag "software engineering", ordered from most recent. Entry count: 38.
# 6 Reasons Why Programming Is Especially Exposed to AI Automation
Tue
27
Oct 2026
Summary: While AI may transform our world in many ways, it seems to me that programming is especially exposed to automation. Below I share 6 specific reasons why.
Many decades ago, people imagined that advances in cybernetics would give us intelligent machines in the form of humanoid robots, speaking in metallic voices and helping people with various physical tasks.
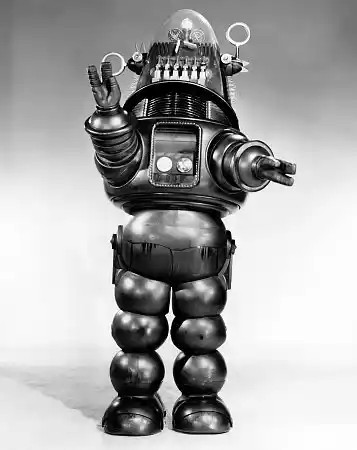
Robby the Robot from "Forbidden Planet", a sci-fi film from 1956
Things have developed differently. AI in the form of LLMs can do some intellectual work and, together with other models, generate realistic speech, images, and video, while general-purpose robots manipulating physical world are still very clumsy and far for being able to help us in everyday chores.
View Joanna Maciejewska’s post on X
I want AI to do my laundry and dishes so that I can do art and writing, not for AI to do my art and writing so that I can do my laundry and dishes. — Joanna Maciejewska
Switching to programming, I still remember reading the book "The Mythical Man-Month" by Fred Brooks a long time ago. The author argued that despite advancements in more convenient, higher-level programming languages, "there is no silver bullet" - no single development can provide an order of magnitude improvements in programming productivity. The argument behind it was that we can reduce the "accidental complexity" of the code (boilerplate code, manual memory management, friction with language syntax, etc.), but there is always "essential complexity" left to handle. If an app needs to provide 5 features, we need to specify all these 5 features fully and precisely how they should work. No matter how high level is the description, it always ends up being... some form of code.
I was thinking back then that a breakthrough would require computers to think like humans: take imprecise, incomplete requirements and turn them into code. My opinion was that programming requires knowledge, skill, and experience, but also analytical thinking and creativity. If computers could ever do it, surely they could do much of the other intellectual work that humans do, leading to changes much broader than just affecting programmers' jobs. I still share this opinion, except now we know it happened.
AI will likely transform our world in many ways, and I don't dare to predict what the future will bring. Right now, however, it seems to me that the nature of programming makes it especially exposed to automation. If we think about why that is, we can identify a few specific reasons:
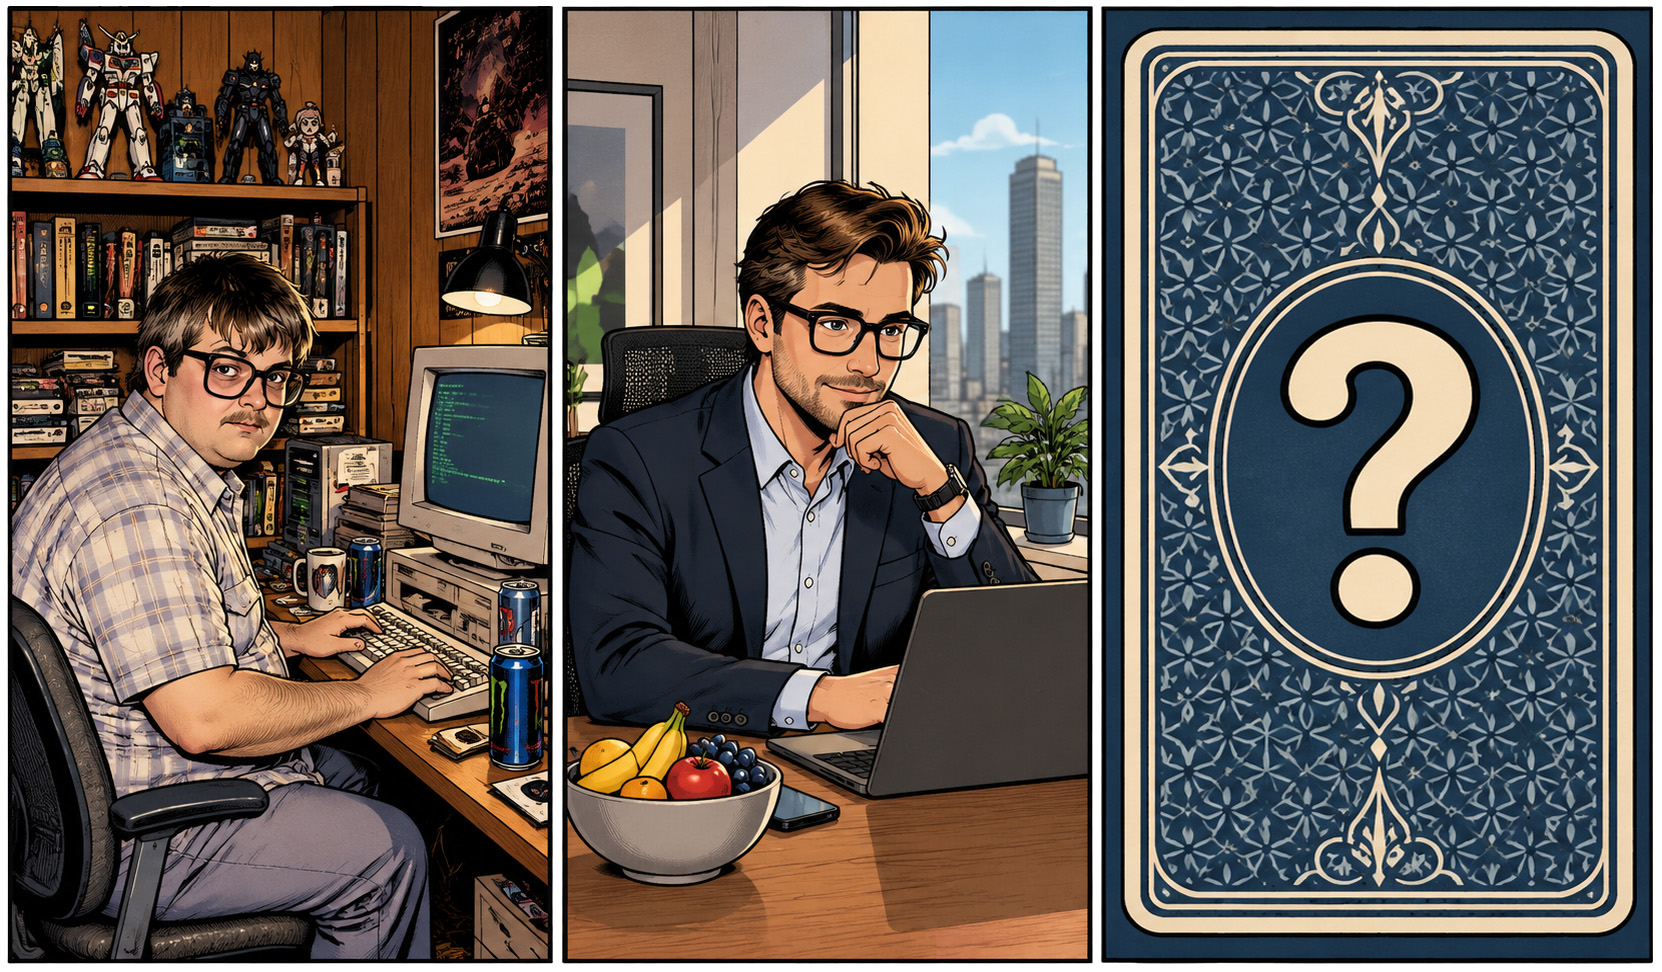
When thinking about my life, I can see that we have gone through several stages in how programmers are commonly perceived. First, when I was a teenager, there was the stereotype of a computer geek. This was before smartphones or social media, so spending time at home with a computer, playing games or learning programming instead of going out to play football, could make someone seem geeky, weird, or socially awkward. Then the perception flipped as mainstream media noticed that working in IT was a good career with high demand and high salaries. Possibly, we are now entering another phase, as the situation of programmers and the public perception of them change. Some young people I've spoken with are already choosing other careers because they don't believe a career in IT is future-proof.
Comments | #ai #software engineering #philosophy Share
# How to do a good code review - a new article
Mon
19
Aug 2024
Today I would like to present my new, comprehensive article: "How to do a good code review". I can be helpful to any programmer no matter what programming language they use. Conducting good code reviews is a skill worth mastering. In this article, we will discuss the advantages and disadvantages of this process and explore the types of projects where it is most beneficial. We will consider the best approach to take when reviewing code, how to effectively carry out the process, which aspects of the code to focus on, and finally – how to write comments on the code in a way that benefits the project. The goal is to ensure that the review process serves as an opportunity for fruitful communication among team members rather than a source of conflict.
The article was first published few months ago in Polish in issue 112 (March/April 2024) of the Programista magazine. Now I have a right to show it publicly for free, so I share it in two language versions:
I wasn't active on my blog in the past months because I took some time for vacation, but also because I'm now learning about machine learning. I may be late to the party, but I recognize that machine learning algorithms are useful tools in many applications. As people learn the basics, the often feel an urge to teach others about it. Some good reads authored by game/graphics developers are: "Machine Learning for Game Devs" by Alan Wolfe and "Crash Course in Deep Learning (for Computer Graphics)" by Jakub Boksansky. I don't want to duplicate their work, so I will only blog about it when I have something unique to show.
Comments | #productions #software engineering Share
# DivideRoundingUp Function and the Value of Abstraction
Sun
25
Sep 2022
It will be a brief article. Imagine we implement a postprocessing effect that needs to recalculate all the pixels on the screen, reading one input texture as SRV 0 and writing one output texture as UAV 0. We use a compute shader that has numthreads(8, 8, 1) declared, so each thread group processes 8 x 8 pixels. When looking at various codebases in gamedev, I've seen many times a code similar to this one:
renderer->SetConstantBuffer(0, &computeConstants);
renderer->BindTexture(0, &inputTexture);
renderer->BindUAV(0, &outputTexture);
constexpr uint32_t groupSize = 8;
renderer->Dispatch(
    (screenWidth  + groupSize - 1) / groupSize,
    (screenHeight + groupSize - 1) / groupSize,
    1);
It should work fine. We definitely need to align up the number of groups to dispatch, so we don't skip pixels on the right and the bottom edge in case our screen resolution is not a multiply of 8. The reason I don't like this code is that it uses a "trick" that in my opinion should be encapsulated like this:
uint32_t DivideRoundingUp(uint32_t a, uint32_t b)
{
    return (a + b - 1) / b;
}
...
renderer->Dispatch(
    DivideRoundingUp(screenWidth, groupSize),
    DivideRoundingUp(screenHeight, groupSize),
    1);
Abstraction is the fundamental concept of software engineering. It is hard to work with complex systems without hiding details behind some higher-level abstraction. This idea applies to entire software modules, but also to small, 1-line pieces of code like this one above. For some programmers it might be obvious when seeing (a + b - 1) / b that we do a division with rounding up, but a junior programmer who just joined the team may not know this trick. By moving it out of view and giving it a descriptive name, we make the code cleaner and easier to understand for everyone. Therefore I think that all small arithmetic or bit tricks like this should be enclosed in a library of functions rather than used inline. Same with the popular formula for checking if a number is a power of two:
bool IsPow2(uint32_t x)
{
    return (x & (x - 1)) == 0;
}
Comments | #software engineering #algorithms #c++ Share
# Avoid double negation, unless...
Thu
11
Jun 2020
Boolean algebra is a branch of mathematics frequently used in computer science. It deals with simple operations like AND, OR, NOT - which we also use in natural language.
In programming, two negations of a boolean variable cancel each other. You could express it in C++ as:
!!x == x
In natural languages, it's not the case. In English we don't use double negatives (unless it's intended, like in the famous song quote "We don't need no education" :) In Polish double negatives are used but don't result in a positive statement. For example, we say "Wegetarianie nie jedzą żadnego rodzaju mięsa.", which literally translates as "Vegetarians don't eat no kind of meat."
No matter what your native language is, in programming it's good to simplify things and so to avoid double negations. For example, if you design an API for your library and you need to name a configuration setting about an optional optimization Foo, it's better to call it "FooOptimizationEnabled". You can then just check if it's true and if so, you do the optimization. If the setting was called "FooOptimizationDisabled", its documentation could say: "When the FooOptimizationDisabled setting is disabled, then the optimization is enabled." - which sounds confusing and we don't want that.
But there are two cases where negative flags are justified in the design of an API. Let me give examples from the world of graphics.
1. When enabled should be the default. It's easier to set flags to 0 or to a minimum set of required flags rather than thinking about each available flag whether or not it should be set, so a setting that most users will need enabled and disable only on special occasions could be a negative flag. For example, Direct3D 12 has D3D12_HEAP_FLAG_DENY_BUFFERS. A heap you create can host any GPU resources by default (buffers and textures), but when you use this flag, you declare you will not use it for buffers. (Note to graphics programmers: I know this is not the best example, because usage of these flags is actually required on Resource Heap Tier 1 and there are also "ALLOW" flags, but I hope you get the idea.)
2. For backward compatibility. If something has always been enabled in previous versions and you want to give users a possibility to disable it in the new version of your library, you don't want to break their old code or ask them to update their code everywhere adding the new "enable" flag, so it's better to add a negative flag that will disable the otherwise still enabled feature. That's what Vulkan does with VK_PIPELINE_CREATE_DISABLE_OPTIMIZATION_BIT. There was no such flag in Vulkan 1.0 - pipelines were always optimized. The latest Vulkan 1.2 has it so you can ask to disable optimization, which may speed up the creation of the pipeline. All the existing code that doesn't use this flag continues to have its pipelines optimized.
Comments | #software engineering Share
# Weirdest rules from coding standards
Sat
28
Sep 2019
Earlier this month I asked on Twitter "what is the weirdest and the most stupid rule you had to follow because of the "Coding Standard"?" I've got some interesting responses. Thinking about it more, I concluded that coding standards are complex. Having one in your project is a good thing because it imposes a consistent style, which is a value by itself. But specific rules are of various types. Some carry universally recognized good practices, like "use std::unique_ptr, don't use std::auto_ptr". Some serve good code performance, like "pass large structures as const& parameters, not by value". Others are purely a matter of subjective preference of its authors, e.g. to use CamelCaseIdentifiers rather than snake_case_identifiers or spaces instead of tabs for indentation. Even the division between those categories is no clear though. For example, there is a research showing that Developers Who Use Spaces Make More Money Than Those Who Use Tabs.
But some rules are simply ridiculous and hard to explain in a rational way. Here are two examples from my experience:
Number 2: Lengthy ASCII-art comment required before every function. In that project we couldn't write an inline function even for the simplest getters, like:
class Element
{
private:
    int identifier;
public:
    int GetIdentifier() { return identifier; } // Illegal!
We had to only declare member functions in the header file, while definition had to contain a specific comment that repeats the name of the function (which is a nonsense and a bad practice by itself, as it introduces duplication and may go out of sync with actual code), and its description (even if the name is self-descriptive), description of all its parameters (even if their names are self-descriptive), return value etc. Example:
/*****************************************************************************\

Function:
    Element::GetIdentifier

Description:
    Returns identifier.

Input:
    None.

Output:
    Identifier of the current element.

\*****************************************************************************/
int Element::GetIdentifier()
{
    return identifier;
}
I like comments. I believe they are useful to explain and augment information carried by function and variable names, especially when they document valid usage of a library interface. For example, a comment may say that a pointer can be null and what that means, a uint may have special value UINT32_MAX and what happens then, or that a float is expressed in seconds. But the comment as shown above doesn't add any useful information. It's just more symbols to type, developer's time wasted, makes code bloated and less readable. It's not even in any standard format that could automatically generate documentation, like with Doxygen. It's just custom, arbitrary rule.
What was the reason behind this rule? A colleague once told me that many years ago the architect of this whole program hoped that they would develop a tool to parse all this code and those comments and generate documentation. Decades have passed, and it didn't happen, but developers still had to write those comments.
The effect was that everyone avoided adding new functions as much as possible or splitting their code into small functions. They were just adding more and more code to the existing ones, which could grow to hundreds of lines. That also caused one of the most obscure bugs I've met in my life (bug number 2).
Number 1: Don't use logical negation operator '!', like: if(!isEnabled). Always compare with false instead, like: if(isEnabled == false).
I understand a requirement to always compare pointers and numbers to some value like nullptr instead of treating them as booleans, although I don't like it. But banning one of the fundamental operators, also when used with bool variables, is hard to justify for me.
Why would anyone come up with something like this? Is it because a single '!' symbol is easy to omit when writing or reading and not so explicit as == false? Then, if the author of this rule suffers from bad sight or dyslexia and a single dash here and there doesn't make a difference to him, maybe he should also define functions Add(), Subtract(), and tell developers to use them instead of operators '+' and '-', because they too are so easy to confuse? Or maybe not... He should rather go do something other than programming :)
Comments | #software engineering #c++ Share
# Technical debt is a good metaphor
Mon
12
Nov 2018
There is this term "technical debt" used in the world of software development as a metaphor to describe poor quality of source code (or the lack of documentation, tests etc.), whether it's a bad overall architecture, quick and dirty hacks in some places, or any kinds of software anti-patterns. It makes the code harder, slower, and less pleasant to maintain, fix, and expand. It's called "debt" because, just as the financial debt, it causes some "interest" that needs to be paid, in form of increased maintenance cost and more bugs to fix, until it's repaid (refactoring or rewrite of bad code, completing work that was missing and left "TODO"). It is most frequently caused by lack of time due to deadlines imposed by business people - lack of time to fully understand the requirements and design good solution, to read and understand the existing codebase, to refactor or rewrite if the code is already bad.
Some people say that "technical debt" is a bad metaphor. There was this one article I can't find now which argued that bad code is unlike real-world debt because we don't need to pay "interest" until we actually need to go back to and modify the specific piece of code where we made a dirty hack. I don't agree with it. Sure things in software development are harder to measure and estimate quantitatively than in the business world, but I think that "technical debt" is a good metaphor. Just like in real life, there are different kinds of debt. It depends on who do you borrow money from:
- Leaving bad code in a place where you and everyone else in the team may never need to look again is like borrowing money from you family or best friend. You know the debt is there, but you may postpone paying it off indefinitely and you will still be fine.
- Leaving bad code in a place where you periodically need to make fixes and other changes is like borrowing money from a bank. You have to periodically pay interest until you repay it all.
- Finally, making ugly hack in a critical piece of code that you touch constantly is like being in so desperate need for money to borrow from mafia. You better repay it quickly or you will get in trouble.
Comments | #philosophy #software engineering Share
# 6th tip to understand legacy code
Sat
20
Jan 2018
I just watched a video published 2 days ago: 5 Tips to Understand Legacy Code by Jonathan Boccara. I like it a lot, yet I feel that something is missing here. The author gives 5 tips for how can you start figuring out a large codebase that is new to you.
These are all great advices. I agree with them. But computer programs have two aspects: dynamic (the way the code executes over time - algorithms, functions, control flow) and static (the way data are stored in memory - data structures). I have a feeling that these 5 points focus mostly on dynamic aspect, so as an advocate of "data-oriented design" I would add another point:
6. "Core data structure": Find structures, classes, variables, enums, and other definitions that describe the most important data that the program is operating on. For example, if it's a game engine, see how objects of a 3D scene are defined (some abstract base CGameObject class), how they can relate to each other (forming a tree structure or so-called scene graph), what properties do they have (name, ID, position, size, orientation, color), what kinds of them are available (mesh, camera, light). Or if that's a compiler, look for definition of Abstract Syntax Tree (AST) node and enum with list of all opcodes. Draw UML diagram that will show what data types are defined, what member variables do they contain and how do they relate to each other (inheritance, composition). After visualizing and understanding that, it will be much easier to analyze the dynamic aspect - code of algorithms that operate on this data. Together, they form the essence of the program. All the rest are just helpers.
Comments | #software engineering Share
# The Virtual Reality of Code
Wed
11
Nov 2015
In my opinion, coding is a virtual reality with its own set of rules unlike in the physical world. In physical world, each thing has its specific location at the moment, things don't appear or disappear instantly, we have laws of energy and mass conservation. Inside a computer, we have data in memory (which is actually linear - 1D) and processors, processes and threads executing instructions of a program over time.
I have been trying for years to imagine some nice way editing or at least visualizing code, which would be more convenient (and look more attractive) than the text representation we all use. I am unsuccessful, because even if we render some nice looking depiction of a function code, its instructions, conditions and loops, drawing all the connections with variables and functions that this code uses would clutter the image too much. It's just like this virtual world doesn't fit into a 2D or 3D world.

Movie depiction of computer programs is often visually attractive, but far from being practical. This one comes from "Hackers" movie.
Of course there are ways of explaining a computer program on a diagram, e.g. entity diagrams or UML notation. I think that electrical diagrams are something in between. Electrical devices end up as physical things, but on a diagram, the shape, size and position of specific elements doesn't match how they will be arranged on a PCB. Logical representation and electrical connections between them is the only thing that matters.
Today it occured to me that this virtual reality of code also has "dimensions", in its own sense. It's evident when learning programming.
1. First, one has to understand control flow - that the processor executes subsequent instructions of the program over time and that there can be jumps caused by conditions, loops, function calls and returns. It's called dynamic aspect of the code. It can be depicted e.g. by UML sequence diagram or activity diagram.
I still remember my colleague at university who couldn't understand this. What's obvious to every programmer, was a great mystery to him as first year's computer science student. He thought that when there is a function above main(), instructions of that function are executed first and then instructions of the main function. He just couldn't imagine the concept of calling one function from the other and returning from it.
2. Then, there is so called static aspect - data structures and objects that are in memory at given moment in time. This involves understanding that objects can be created in one place and destroyed in another place and at later time, that there may be a collection of multiple objects (arrays, lists, trees, graphs and other data structures), objects may be connected to one another (the concept of pointers or references). Various relationships are possible, like one-to-one and one-to-many. In object-oriented methodologies, there is another layer of depth here, as there are classes and interfaces (with inheritance, composition etc.) and there are actual objects in memory that are instances of these classes. It can be depicted for example by entity diagram or UML class diagram.
3. Finally, one has to learn about version control systems that store history of the code. This adds another dimension to all the above, as over successive commits, developers make changes to the code - its structure and the way it works, including format of data structures it uses. Branches and merges add even more complexity to it. GUI apps for version control systems offer some way of visualizing this, whether it's showing a timeline with commits ("History") or showing who and when commited each line of a file ("Blame").
There is even more to it. Source is organized into files and directories, which may be more or less related to the structure of contained code. Multithreading (and coprocessing e.g. with GPU, SIMD, and all kinds of parallel programming) complicates imagining (and especially debugging!) control flow of the program. Program binaries and data may be distributed into multiple programs and machines that have to communicate.
It fascinates me how software is so multidimensional in its own way, while so flat at the same time (after all, computer memory is linear). I believe that becoming a programmer is all about learning how to imagine, navigate and create stuff in this virtual reality.


